
Teams often import social-listening habits into AI search: chase polarity, celebrate "positive," panic at "negative," ignore the sentence that actually kills preference.
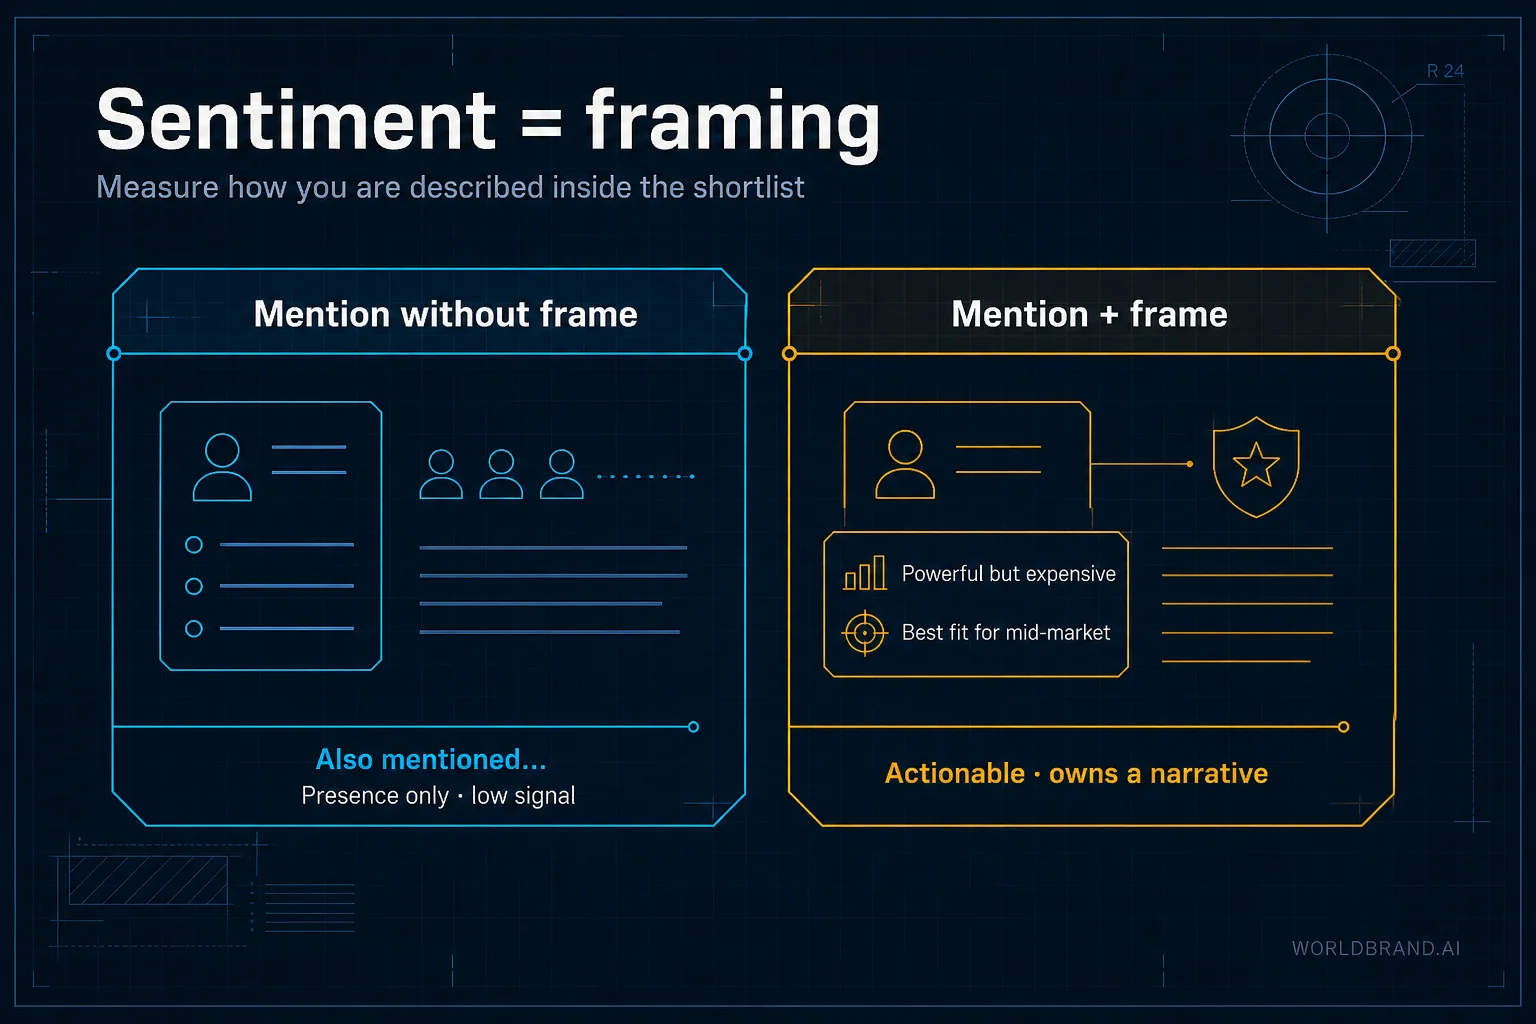
In answer engines, sentiment is framing inside a shortlist. Being mentioned as "powerful but expensive" can be worse than a polite omission. Brand Wiki surfaces sentiment alongside presence for a reason—this guide is how to measure it without fooling yourself.
What to measure (and what not to)
| Score this | Do not treat as primary truth |
|---|---|
| Sentiment conditional on mention (no mention = no score) | A single glowing chat with a branded prompt |
| Recurring adjective clusters: price, complexity, modernity, trust, risk | Unlabeled averages across junk prompts |
| Peer-relative framing on comparison prompts | Sentiment without presence |
| Engine-level disagreement (one model warm, another cold) | Polarity alone when the damaging word is a specific trade-off |
| Whether the frame helps or hurts the buying story (fit vs. deterrent) | Relabeling a bad week by editing prompt wording |
Build a framing codebook
Before you trust the dashboard, agree on labels your team will track manually for a calibration week:
- Premium / expensive / affordable
- Easy / complex / enterprise-only
- Innovative / legacy / safe
- Trusted / unknown / controversial
- Best-fit / also-ran / risky
Then compare human labels to AEO Intelligence sentiment outputs on the same locked set. Calibration prevents theology arguments in QBR. Keep the codebook short—eight to twelve labels beats a thesaurus.
Store examples next to each label: a verbatim phrase from an engine answer, the prompt ID, and the peer set. That archive becomes training material for new analysts and a defense when someone wants to "relabel" a bad week.
Prompt families change sentiment physics
| Family | What sentiment actually reflects |
|---|---|
| Category prompts | Category stereotypes ("legacy OEMs," "hot startups") |
| Comparison prompts | Relative framing; watch contrastive language |
| Best-of prompts | Omission often matters more than mild negativity |
Always report sentiment by family, not as one magical index. A warm category score can hide a brutal comparison frame.
How to score without lying to leadership
Use a three-layer readout:
- Presence — mention rate on the locked family
- Frame mix — share of mentions carrying each codebook label
- Preference proxies — first-mention, recommend language, trust adjectives (when present)
Never average layer 2 across prompts with zero mentions. Never blend branded and unbranded prompts in the same chart. If leadership asks for "one sentiment number," give them one number plus the family and peer set it came from—or refuse the chart.
Operating rules
- Lock the prompt set; never "fix" wording after a bad sentiment week.
- Pair every sentiment swing with citation and peer checks.
- Convert repeated negative frames into evidence tickets (pricing pages, docs, reviews).
- Use Brand Wiki when you need brand context behind a nasty adjective.
- Escalate only frames that hit revenue narratives—not every slightly cool paragraph.
- Re-measure the affected cluster two weeks after a repair ships—not the entire internet.
Example readout
Bad: "Sentiment improved."
Better: "On 18 unbranded comparison prompts where we are mentioned, 'expensive' framing fell from 11 → 4 occurrences after pricing-language cleanup; Peer B still owns 'easy to implement' on implementation prompts."
Best (ticket-ready): "P1 ticket closed: pricing FAQ + comparison table. Re-measure date on the books. Next frame to attack: 'complex' on mid-market category prompts."
Common failure modes
| Failure | Why it misleads |
|---|---|
| Branded prompt theater | "Is Brand X great?" produces praise that never appears in category demand |
| One-engine obsession | Optimizing the warmest model while the coldest one owns your buyer's workflow |
| Campaign as fix | A launch film will not erase a stale pricing page that every citation still points at |
| Sentiment without owners | If no DRI owns the frame, the chart becomes entertainment |
FAQ
Who should own sentiment readouts and frame repairs?
The AEO DRI calibrates the codebook and reports frame mix by family; fact-class owners (PMM, brand, PR) ship the evidence tickets. Sentiment without a named DRI becomes a QBR decoration.
How do we attach sentiment to the weekly AEO rhythm?
Add frame-mix review to the diagnose block—one family, one swing, one ticket. Re-measure only the affected prompt cluster two weeks after a repair ships; never relabel a bad week by editing prompts.
What should teams refuse when leadership asks for "one number"?
A blended polarity score across branded and unbranded prompts, or any average that includes prompts with zero mentions. Offer one number with family, peer set, and conditional-on-mention context—or decline the chart.
What is the fastest way to fool yourself?
Branded prompt theater: chasing praise on "Is Brand X great?" while unbranded category prompts still frame you as expensive, legacy, or absent.
Where brand.com fits
- Brand Wiki — visibility, narrative, sources, and competitive presence on locked prompts
- Brand Wiki — structured brand profiles and the public facts models can cite
Bottom line
Sentiment in AI answers is a narrative control problem, not a vibes problem.
Measure framing on locked prompts, calibrate labels, and repair the evidence that teaches models to insult you politely.