

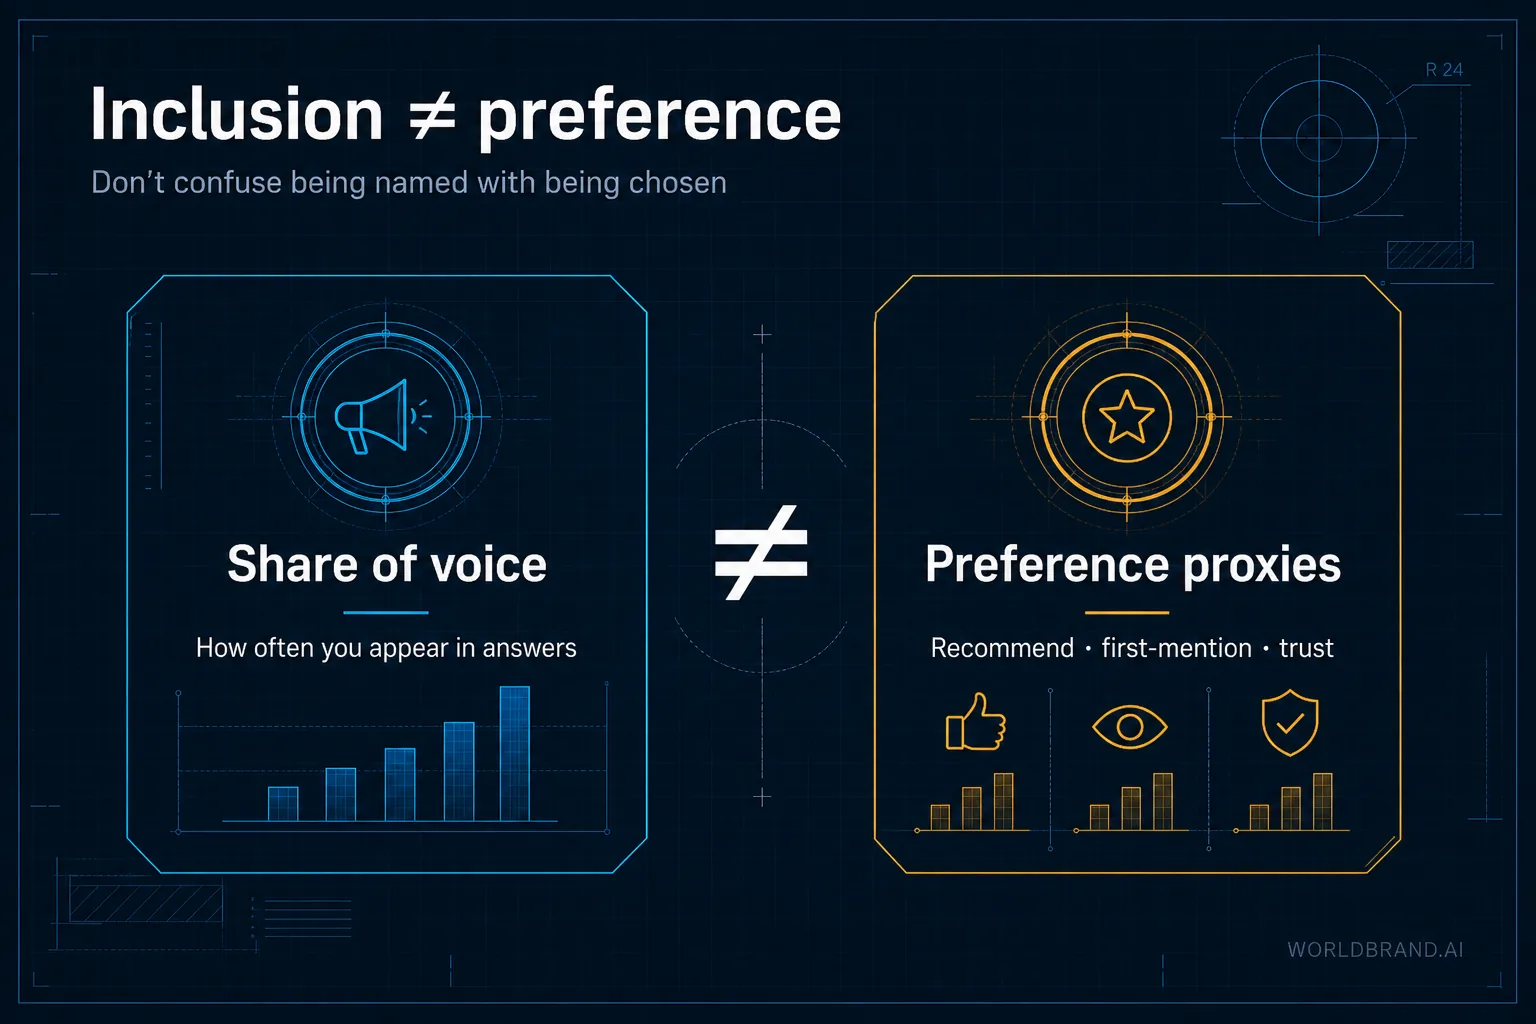
AI share of voice measures inclusion—how often your brand appears on a fixed prompt set. Preference is different: who gets recommended with trust, fit, and proof.
SOV gets you into the paragraph. Preference gets you the verb "recommend."
Collapsing the two makes teams celebrate mentions beside competitors who still win the recommendation sentence. Measure inclusion and preference proxies separately on every scoreboard.
What SOV actually captures
On a locked prompt set in Brand Wiki, SOV typically reflects:
- Presence across category / comparison / best-of families
- Relative mention frequency vs a named peer set
- Sometimes position-ish signals inside a paragraph (fragile—handle with care)
SOV does not automatically capture willingness-to-buy, fit, or trust. It answers "did we enter the shortlist?"—not "would a careful buyer choose us?"
How does preference leave fingerprints?
Look for preference-like patterns in answers:
- Named first with a clean use-case fit
- Recommended under constraints ("if you need X, pick Y")
- Cited to strong proof pages
- Framed with trust / performance adjectives—not "also-ran" language
A brand can lead SOV and still lose preference if every mention is "legacy alternative." That is why sentiment-as-framing belongs next to SOV, not instead of it.
How to report both without confusion
Use two lines on every scoreboard:
- Inclusion — mention rate / SOV by prompt family
- Preference proxies — recommendation language rate, first-mention rate on best-of prompts, positive-trust framing among mentions
Never average them into one "AI brand score" that nobody can debug. If leadership demands a single chart, give them a dual-axis readout or two adjacent numbers with the peer set and prompt-family labels printed in the footer.
Calibration week (do this once)
Before you trust preference proxies:
- Sample 30 answers where you are mentioned on best-of / comparison prompts
- Human-label: recommend / qualified recommend / neutral include / negative include
- Compare labels to automated framing flags
- Lock the codebook; do not relabel after a bad week
Without calibration, "preference" becomes another vibes argument.
Example readout
Bad: "AI SOV is up 4 points—we're winning."
Better: "Unbranded category SOV vs peer set rose 12% — 16%. On best-of prompts where we are mentioned, first-mention rate is 18% (Peer A: 41%), and 'legacy' framing appears in 7 of 22 mentions. Inclusion improved; preference did not. Next ticket: comparison page + retire deprecated positioning language."
What are the strategy implications?
| Pattern | Likely diagnosis | First move |
|---|---|---|
| High SOV, low preference | Narrative and proof problem | Fix framing and citations |
| Low SOV, high preference when present | Discovery problem | Category language and corroboration |
| Low both | Category strategy or measurement set is wrong | Revisit prompt families and peer set |
| High both | Defensible position | Defend consistency; watch peer citation attacks |
Pair with Brand Wiki context and brand structure so you know whether preference gaps are messaging or deeper brand architecture. When value looks strong but preference proxies are weak, you are watching the split scoreboard problem—see Brand Value vs. AI Share of Voice.
FAQ
Who owns the dual scoreboard?
The AEO lead or brand analyst publishes both lines weekly—never delegated to a single "AI SOV" KPI owner. If only inclusion gets reported, preference decay will hide inside a green chart until a competitor wins the recommendation sentence.
What is the anti-pattern in leadership readouts?
Blending inclusion and preference into one composite "AI brand score." It feels decisive and is undebuggable. If leadership insists on one slide, use dual-axis or adjacent numbers with peer set and prompt-family labels in the footer—not a weighted average nobody can explain.
When should we rerun calibration?
Once at setup, then only when you change prompt families, peer sets, or automated framing logic—not after a bad week to relabel answers into a nicer story.
What should we stop doing when SOV rises?
Stop declaring victory. A rising inclusion chart with flat or falling first-mention rate on best-of prompts means you entered more shortlists but still lost the recommendation. That warrants a framing ticket, not a celebration deck.
Where brand.com fits
- Brand Wiki — visibility, narrative, sources, and competitive presence on locked prompts
- Brand Wiki — structured brand profiles and the public facts models can cite